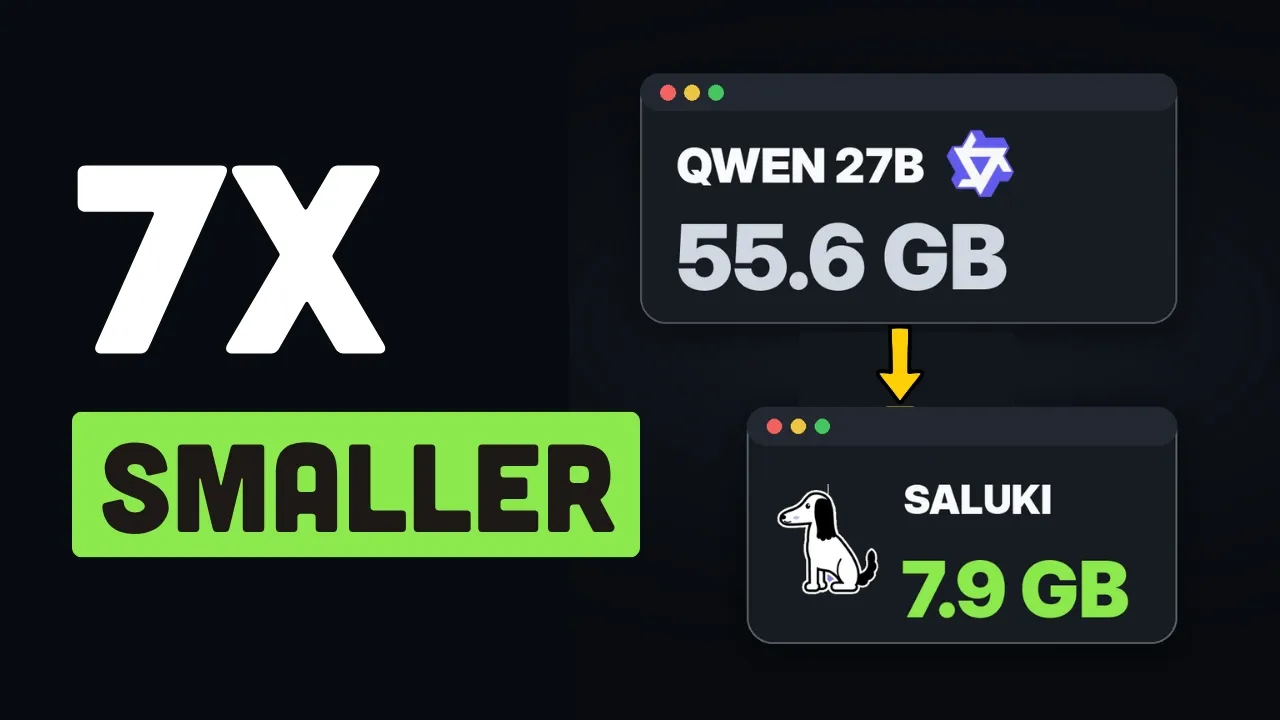
This Tiny Qwen 27B Model Runs on a 12GB GPU
 Better Stack
Oct 24, 2026 08:30
Create an account to hide videos, mark them watched, or save them to Don't Miss.
Create an account to hide videos, mark them watched, or save them to Don't Miss.
Create an account to hide videos, mark them watched, or save them to Don't Miss.
Chapters
Underdog Saluki 27B is a new 7.9GB local AI model that compresses the original 55.6GB Qwen 27B model using aggressive 2-bit quantization, yet reportedly outperforms the full-size model at tool calling. But there's a catch.
In this video, I test Saluki 27B locally using llama.cpp, parallel tool calls and JSON output, memory usage and inference performance, and show how such a heavily compressed LLM can achieve higher tool-calling benchmark scores while losing accuracy in math, coding, and reasoning.
🔗 Relevant Links
Hugging Face - https://huggingface.co/ConwayResearch/Underdog-Saluki-27B-1.0
❤️ More about us
Radically better observability stack: https://betterstack.com/
Written tutorials: https://betterstack.com/community/
Example projects: https://github.com/BetterStackHQ
📱 Socials
Twitter: https://twitter.com/betterstackhq
Instagram: https://www.instagram.com/betterstackhq/
TikTok: https://www.tiktok.com/@betterstack
LinkedIn: https://www.linkedin.com/company/betterstack
📌 Chapters:
Science & Technology
#Underdog Saluki 27B
#Saluki 27B
#Underdog Saluki review
#Saluki 27B benchmark
#Qwen3.8 27B
#Qwen 27B
#Qwen 27B quantization
#2 bit quantization
#2 bit LLM
#7.9GB AI model
#local AI
#local LLM
#run LLM locally
#local AI agents
#Unsloth
#AI tool calling
#LLM function calling
#BFCL benchmark
#llama.cpp
#Ollama
#GGUF models
#AI model compression
#small language models
#Qwen vs Saluki
#Ternary Bonsai 2